Last year Marks & Spencer, Jaguar Land Rover, the Co-op, Harrods, and several other big businesses hit the headlines for all the wrong reasons. They were all severely impacted by cyber attacks which continue to increase in sophistication, severity, and the scale of disruption caused.
Following a craftily timed attack over the Easter weekend, M&S was forced to stop all its online sales. It experienced difficulties with contactless payments in-store. Its shelves lay empty due to disruption caused to its logistics systems. Its I.T. team had to work around-the-clock for months to repair damaged I.T. infrastructure. All caused by a hack that their Chief Executive later confirmed had been instigated “by human error” 1.
Contents
What’s the true cost?
Marks & Spencer was forced to suspend its online orders for six weeks. Its click-and-collect service was out-of-action for almost four months. Its first-half reported profits plummeted 99% year-on-year from £391.9m to £3.4m 2. The impact on group operating profit was confirmed to be around £300m 3.
Fast forward to Christmas and M&S’s fashion sales were disappointing, partly attributed to “the long-tail impact on stock data and management following the incident” 4. Meanwhile its key competitor, Next, recorded a bumper Christmas “thanks to its slick online service”.
Jaguar Land Rover had to pause car production for five weeks, causing widespread delays to its supply chain which onwardly affected 5,000 businesses.
The total estimated economic cost of the JLR attack is £1.9 BILLION 5 making it the most economically harmful cyber event in UK history.
Alongside the potentially irreparable damage caused to their brand reputation, the longer it takes for these companies to recover, the greater the revenue loss …
- failure to meet compliance requirements can incur financial penalties;
- inability to invoice or the need to stop production can damage supplier relationships;
- loss of revenue can force staff redundancies.
Sadly this means businesses that can’t cope with the fallout from the attack may end up falling into administration. Which is what happened to the 158-year old haulage firm, Knights of Old back in September 2023 6.
For those companies that do manage to stay afloat, the associated costs of recovery can still be crippling.
How to remain operational
The key to ensuring your business can continue to operate when faced with the growing threat of ransomware and other cyber security or data-related incidents is to implement solutions that keep your data usable and available whilst meeting cyber security best practice.
This is specifically the case with ransomware, where threat actors will almost certainly compromise your backup environment first before they look to seed malware into your production environment. According to 2025 research from Veeam, 89% of ransomware attacks were on the target’s backup repository. 7
It’s not just about being able to get your data. It’s being able to get your data in a time period that is acceptable for your organisation.
The key point is identifying what data you need to be able to recover and in what timeframe it needs to be recovered?
What’s true immutability and why does it matter?
Cloud repositories such as AWS have been offering immutable security since mid-2018 8. But that’s really where things have had to change.
Previously any critical data would be recovered from an on-premise repository, with the cloud really as the last line of defence.
But nowadays many existing on-premise repositories are no longer fit for this purpose. Why? Because they are not truly immutable.
Immutability is a nuanced term that has been bandied around. It’s important to determine whether what is being termed as immutable is genuinely i.e. truly immutable or not.
Many existing on-premise repositories are not truly immutable. If you’re hit with ransomware, your backup environment including your on-premise repositories, will typically be the first thing that’s attacked. Because if an attacker can compromise your backup and stop you being able to recover, you’re much more likely to pay the ransom.
We estimate over 90% of on-premise repositories currently in use will not be immutable. It’s a specific feature-set for purpose-built repositories. To be fair, most of those types of products don’t even claim to have any level of immutability. But if they do, it will be immutability purely at a data level. Not at the storage level. Or to put it another way, there’s immutability at the application level but not at the appliance level.
What that means is if someone gets hold of the admin credentials for your on-premise box, they can immediately just override any immutability setting. Simply turn it off. And then proceed to delete all the “immutable” data files you had stored on it.
If you can do it, someone else can do it too
If you can go in at an admin level and remove the immutability functionality, delete the setting, override it, whatever, then essentially you’ve got full access to the data. You could go in and remove buckets, remove user accounts, delete the entire data store. So there would be nothing there, immutable or otherwise.
It may as well not have been “immutable” (in name only) in the first place.
If someone can access your appliance with credentials, which is normally the case with the majority of existing on-premise repositories, they can get into the data layer and delete all of the immutable copies within that appliance.
True immutability means your data can’t be deleted, removed, overwritten, encrypted, nor in any way modified, by anybody, for a pre-determined period of time.
Your data cannot be overwritten by anyone. Not by nefarious actors, not by the appliance manufacturer. Not even by your own admin teams.
If you or anyone in your organisation is able to access the appliance with root or administrator-level credentials, it’s not truly immutable.
How do I ensure I have “true immutability”?
This feature is only available if you have a dedicated immutable appliance. In many cases people think their appliance or hardened repository is immutable but it’s not.
The majority of systems out there from the normal storage vendors do not have this failsafe. That’s not what they offer. They do not have this process in place for true immutability.
These solutions will support data immutability – i.e. the backup you take is immutable at a data level – but they’re not immutable at the appliance level – so if anybody can get access to it, they can just go in and delete all of your immutable backups. And then still be in a position to hold you to ransom!
If you’ve got a truly immutable appliance, then you as an admin user will not have credentials to access the storage level.
To do that, you would typically have to go back to the vendor, pass various security tests to give that vendor remote root-access into your box, open up a maintenance window, and permit the vendor to go onto the appliance and override those settings.
So you need two parties, both in agreement that somebody needs to access the appliance level. You as a user cannot go and do it all yourself. And there are so many security and verification obstacles to undertake that only a genuine admin could do so.
In the meantime, you’d have multiple opportunities to deny the request, identify you were under potential attack, verify the request being made wasn’t a legitimate one etc.
What truly immutable appliances are available?
Truly immutable on-premise storage options include products from Cloudian, Exagrid, ObjectFirst, and Scality.
After conducting our own due diligence around all the truly immutable on-premise backup repositories, with enterprise-grade scalability, and cost accessibility, available on the market, Autodata chose to partner with Scality to create our Autodata Rapid Recovery Vault (RRV).
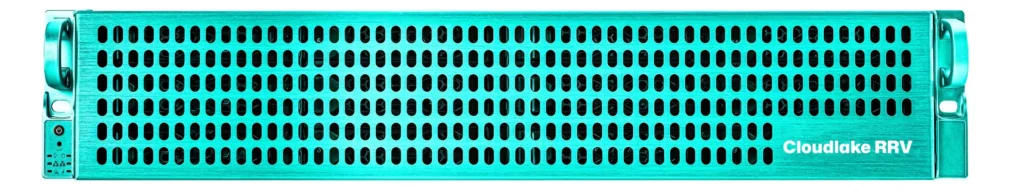
As its name suggests, the RRV is designed with resilience and speed in mind, enabling rapid recovery of critical workloads even during a severe ransomware event.
But in developing the RRV with Scality, Autodata has ensured that organisations, regardless of their size or market vertical, can benefit from a simple and secure on-premise repository that seamlessly integrates with any leading backup tool for truly immutable backups.
The key benefits of our Autodata Rapid Recovery Vault include:
- Scalability: from 20 TB to 11.3 PB
- True Immutability: across five core layers
- Resilience: node-level fault tolerance with true clustering
- Performance: 10–25 GB networking and SSD/NVMe storage
- Fully Managed: including updates, patching, and proactive support
- Cost Efficiency: attainable for any business size
Get in touch if you want more information about RRV. Other immutable on-premise storage appliances are of course available (as listed above). We just think ours is the best!
What about the appliance I already have?
Traditional storage vendors like HPE/Dell/NetApp/Pure DO NOT offer true immutability.
These vendors will say their appliances can “support” data immutability and, sure, you can take a backup and make that backup immutable at the data level.
But it’s not immutable at the appliance level.
So when someone/anyone gets access to your appliance, they can simply go in and delete all your “supported” backups.
It’s important to understand the semantics at play….
A lot of people say immutable when they’re only referring to immutability at one specific level i.e. the data level. But if you can override it elsewhere, it’s not actually immutable, simple as that!
If you have a solution that isn’t truly immutable but instead just supports immutability, then if someone gets hold of your admin credentials, they can go into your appliance, delete your backups, override your immutability settings, and then hold you to ransom.
Instead you need to send your backups, using software that supports immutability, to a dedicated immutable target appliance.
Can’t I stick everything in the cloud and recover from there?
Well yes, you could. It depends on the type of data-related disruption* you are faced with and how quickly you need to get back up and running.
Recovering purely from cloud repositories will be slow, limited by network capacity, and the time it takes to validate each dataset.
Often in the case of ransomware, one of the first steps is to “cut the cable” and disconnect from all external networks to contain the threat, prevent data exfiltration, and limit lateral movement. So you may not even be able to get access to your cloud until that external connectivity is re-established.
It’s still a strategy, but it’s a risky one if your recovery timeline is the real killer.
You’re just scaremongering!
We’re not exaggerating. We’ve seen it first-hand…
Companies with robust security frameworks, reputable on-premise backup systems, and immutable cloud repositories, who have been hit with ransomware, had to disconnect from the network to avoid further spread of the infection, waited over one week for the network pipes to be opened, then another four to six weeks for full recovery from the cloud:
- rebooting their firewall to re-establish the connection to their cloud repositories;
- restoring VMs one-by-one into a sandbox;
- flattening on-premise systems wherever possible to help free up bandwidth;
- checking all the recovered data is clean;
- before then restoring it all back into their core live-production environment to be finally back up and running.
Their immutable cloud backups did a great job protecting their data … but unfortunately that didn’t help spare their time.
Let’s pluck a quote from someone who really knows what he’s talking about in the UK space, like the Global Head of Cyber at Hiscox9:
“No business can afford to underestimate the devastating impact a cyber-attack can have. Cyber-attacks don’t just disrupt day-to-day operations; they can threaten the very survival of a business. The financial fall-out, from crippling fines to lost customers or soaring costs, can push even the most resilient business to the brink. On top of this, the stress and long hours required to recover can impact staff morale and even lead to burnout.”
Eddie Lamb
Global Head of Cyber at Hiscox Insurance
But what about “Cloud First”?!
Cloud first doesn’t mean cloud only.
Gone are the days when you would, could or should store ALL your data on-premise. The volume of data we process is just too great and as we have seen with the current DRAM shortages, AI will only serve to expand that further!
Granted a streamlined, agile, scalable, cloud-first architecture for your primary data storage promotes effective operation in many business areas.
But your critical data, along with any time-sensitive workloads reliant on low latency, or subject to compliance parameters, should be stored locally so they are available locally, and therefore available to recover quickly, for all the reasons listed above.
If it’s not critical and it’s not time-sensitive you can just recover it from the cloud.
Adopting a hybrid infrastructure strategy that matches the goals and requirements of your business’ activity is crucial to maintain its operational effectiveness.
Is your Cloud within reach?
That’s a valid question when you consider the anatomy of a ransomware attack …
Day Zero
You find out you’ve been hit by a ransomware attack, whether that’s because you notice there’s an anomaly in your system, you’ve lost data, your security software has alerted you, you’ve been locked out, or you’ve received a ransom demand.
You try to do some level of immediate mitigation yourself, going to check your backups. Meanwhile your management team contacts its external Incident-Response team and puts the wheels in motion around the regulatory compliance requirements of reporting the breach.
Then word comes back from the external IR team: UNPLUG EVERYTHING IMMEDIATELY!!!
Week 1 / Days 1-3
The IR team parachutes in and starts trying to identify the cause of the breach, scoping all your systems, figuring out how the attackers got in, determining what systems, services and data has been affected or infected. Asking questions. Demanding answers. Everything’s being CONTAINED.
Week 1 / Days 4-6
The compromise has been detected, identified and documented. The IR team starts eradicating the ransomware and remediating the vulnerabilities that allowed it to happen in the first place. Providing your cloud environment hasn’t been infiltrated, and the IR team are confident you won’t be reintroducing any threats into your environment, you’re given permission to reconnect to the outside world.
Week 1 / Day 7
Week 1, Day 7: You are finally allowed to reconfigure your firewall / apply a factory reset / restore from a clean configuration backup and reopen all your ports.
Weeks 2 / 3 / 4 / 5 / 6+
You painstakingly restore all your VMs from the cloud, machine-by-machine until your core systems are all back up and running; with yet more work needed to get back to where you were before the attack happened.
All of which assumes in your average day job you are just sitting around twiddling your thumbs with nothing to do, which let’s face it, couldn’t be further from the truth! But unfortunately that’s the assumption everyone else in your business will make.
So once you have done all the above, which has taken up all your and your team’s time, you still have weeks of BAU backlog to catch up with.
And that’s negating more than just one data-related disruption* having occurred during this period.
*Data-related disruptions
Obviously ransomware is the most feared/talked about as it’s so invasive. However it’s not the only data-related business disruption that can and does happen.
Other data-related disruptions include:
- other malicious cyber attacks;
- insider threats;
- permission/privacy misconfigurations;
- hardware failure;
- system or network outages;
- corrupted backups;
- loss of encryption keys;
- failed data recovery;
- accidental deletions.
In almost every case, recovering the critical elements affected by the disruption from the cloud will take longer than from an on-premise device.
And inevitably, in every case, time is money!
When speed is of the essence
With a dedicated on-premise immutable appliance, you can start looking at your data and doing restorations almost immediately.
You can do multiple machines restorations simultaneously and you can do these very, very quickly.
With ransomware attacks, there’s no risk of propagating the ransom demand because you’re not allowing that data to leak out externally.
You’re still disconnected from the outside world during containment and you/your IR team still need to identify the root cause. But crucially you won’t be waiting to reconnect before you can restore. Recovery performance is optimised and restoration can begin immediately.
You can start looking at your data.
You’re not waiting to connect to the outside world.
You don’t need your firewalls to be checked and recommissioned before you can access your backups.
How much quicker?
You may be able to start restoring from your immutable on-premise unit while waiting for the IR team to arrive or they can start it as soon as they do.
Performance-wise, as it’s on-premise, it’s all at your local network speed or your storage network speed. You’re not suddenly in the situation where you’re at the mercy of bandwidth connecting up to the cloud.
So it’s much faster from a data transfer point of view.
We typically see recovery times reduced by one to three weeks compared with conventional setups, but it could be multiple weeks depending on the complexity of your system, the severity of the attack, and obviously things like the amount of bandwidth you have available.
Rack and stack = good to go!
Getting a truly immutable on-premise repository isn’t complicated nor costly.
The setup time is minimal. You just need to have a backup tool that can export data to an S3 object store appliance. Once you’ve got it connected to your network, your backup- tools will just see it as another storage repository.
The process is just like interacting with any other repository on-premise or in the cloud. So the learning curve and the operations overhead is minimal to nothing.
It’s pretty seamless and should only take minutes and hours, not days or weeks.
It’s far less onerous than using a (mutable) Linux hardened server as a repository which requires I.T. resource and skill-sets in-house to be able to maintain the box.
You do also need to ensure your immutability feature is turned on though. With some solutions, that actually impacts performance so it ends up getting turned off!
I don’t have the resource to manage another appliance
To avoid any one individual or multiple individuals with the organisation having the responsibility of keeping the system up and running, wherever possible, Autodata recommends you looking at putting a fully managed solution in place.
Autodata’s Rapid Recovery Vault powered by Scality is a fully managed solution. So you don’t have to have any expertise and don’t have to have the skill set in-house.
This mitigates the risk of your own people with the skill set leaving (particularly given the shortage of I.T. resource in the UK market at present) and provides you with the reassurance that your appliance is always considerately updated and patched.
Additionally as our RRV uses a completely different type of disc technology, the rebuild time in the event of a hardware failure, is very, very quick compared to a similar appliance that uses RAID technology. With our RRV your risk exposure while recovering from a fault is hours, compared to days.
What’s the storage capacity?
if you’ve got 100 terabytes of data on premise, 50TB of it might be critical and time sensitive, 50TB of it might just be data that’s you want to retain but isn’t critical/time sensitive.
You could have an RRV or similar that would be large enough to store the 50TB of critical data. You might then have another on-premise repository for your non-critical data and/or have it stored in the cloud.
The current maximum capacity of Autodata’s Rapid Recovery Vault is 11,376 TB. So you can have six individual nodes of 2 Petabytes each, equating to 11.3PB of total usable storage within just one cluster.
*Our dedicated immutable storage appliances are available with prices starting from £8,395 (costed by appropriate appliance size).
How to pitch this to the C-Suite
Time is money. The conversation around backups with the C-Suite needs to be shifted away from technical backup specifications towards data resilience, risk mitigation, and financial impact.
Cost is the amount of time it takes to recover, because all the while you’re in a situation where you’re trying to recover, your business is losing revenue.
Your C-Suite will want to talk about things like the RTO (Recovery Time Objective) and RPO (Recovery Time Objective) in relation to any new solution:
Faster RTOs – having reliable, clean backup copies ensures teams can restore systems and data immediately.
Higher RPOs – with an immutable backup system in place, you can back up more frequently and retain restore points securely, which minimises data loss.
It’s crucial that you have all your critical/time-sensitive data and line-of-business applications stored safely and immutably on-premise and in data centres you control, rather than it all sitting within a hyperscaler.
This also ensures you are following the all-important 3-2-1-1-0 backup rule.
Data Resilience is Risk Mitigation
If you lose the ability to recover your critical systems, the net effect could be that your staff and suppliers can’t access the systems they need, disrupting your supply chain, and your customers won’t be able to access your customer-facing systems either, ultimately stopping any revenue being driven through the customer base until they are fixed.
And it’s not just the immediate revenue loss to worry about.
Your C-Suite should also be concerned about losing future revenue from customers who may not come back to them again once their systems have gone back online: Next vs M&S at Christmas 2025 being a case in point. 10
So the cost is really immeasurable, with regards to the amount of downtime. That’s why it’s essential to do everything you can to try and mitigate the length of time between facing a disruption to getting all your core lines of business applications up and running.
Not to mention what arguably will have the longest legacy … the damage to your brand reputation, the erosion of client trust. Brands must work really hard to recover from this with Customers thinking …
- you don’t have proper cybersecurity protections in place
- my personal data, home address, bank details, order history, isn’t safe in your hands
- you’re not as trustworthy as your nearest competitor
- I’m just as happy giving my business to someone else now
It all goes back to SPEED being your most necessary recovery vector.
Although COST on both sides of the argument (i.e. the cost of having it versus the cost of not having it!) is also important.
- https://www.reuters.com/business/retail-consumer/ms-says-cyber-attack-was-result-human-error-declines-comment-ransom-2025-05-21 ↩︎
- https://www.bbc.co.uk/news/articles/c93x16zkl9do ↩︎
- https://supplychaindigital.com/news/m-s-cyberattack-nexts-profits-expose-the-real-breach-cost ↩︎
- https://www.theguardian.com/business/2026/jan/08/ms-christmas-food-sales-soar-but-clothing-suffers-from-cyber-attack-fallout ↩︎
- https://www.bbc.co.uk/news/articles/cy9pdld4y81o ↩︎
- https://www.bbc.co.uk/news/uk-england-northamptonshire-66927965 ↩︎
- https://www.computerweekly.com/news/366628213/Data-resilience-critical-as-ransomware-attacks-target-backups ↩︎
- https://aws.amazon.com/about-aws/whats-new/2018/11/s3-object-lock/ ↩︎
- https://www.hiscoxgroup.com/news/press-releases/2025/29-09-25 ↩︎
- https://supplychaindigital.com/news/m-s-cyberattack-nexts-profits-expose-the-real-breach-cost ↩︎